About
A score you can argue with
webmcp-tool.com measures whether an AI agent can read, understand and operate a website. It is free, it needs no account, and every finding shows the evidence it was based on so you can check it yourself.
Why the score is shaped the way it is
WebMCP is the reason this site exists and it carries the largest single pillar, 25 of 100 points. It is not the whole score. Adoption of the standard outside demonstrations is still close to zero, and a measurement that returned nought for nearly every site on the web would be accurate and useless.
So the score covers the whole chain: being reachable, being understood, being operable, and then being callable as tools. The first three help with every agent that exists today. The fourth is where the next two years go. The full methodology is public and generated from the code that runs it.
What it deliberately does not do
- It does not call other tools’ APIs. Every check here is our own implementation, run against your site. Where other projects publish a check catalogue, that told us which signals exist — the measurement is ours.
- It does not scan private hosts. Bare IP addresses, localhost and internal domain suffixes are refused. A scanner that will fetch any address on request is a probe into someone’s network, and we are not going to run one.
- It does not gate the result. No email, no sign-up, no drip sequence for a number you can get from a command line.
- It does not execute your JavaScript. That is the point — it is what most agent crawlers do. It also means we can miss tools registered at runtime, and we say so on the methodology page.
Who runs it
Three co-founders of yawusa UG in Berlin, who also build this kind of thing for a living: server rendering applications that were never built for it, designing a tool set worth registering, and getting a discovery document past a robots.txt that hides it. That is a conflict of interest worth naming, so here is how we handle it: the methodology is public and generated from the rule set, every finding carries its evidence, and where a problem is straightforward we say plainly that you should fix it yourself rather than hire anyone.
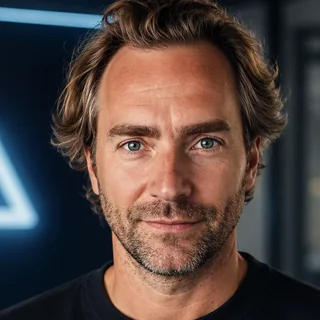
Gorden Wübbe
Co-founder
Years of work on how sites get found and read by search engines. The first two pillars of this score — whether an agent can reach a page at all, and whether it can understand what it finds there — are that same work pointed at a different reader.
LinkedIn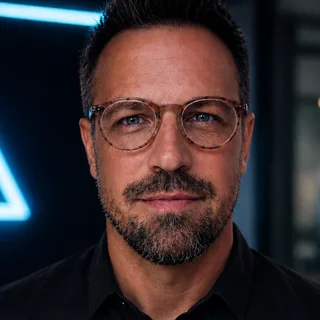
Tobias Sander
Co-founder
Product and integration work: connecting agents to systems that already exist. That is where the operability and WebMCP pillars come from — a tool an agent can call is an integration question long before it is a markup question.
LinkedIn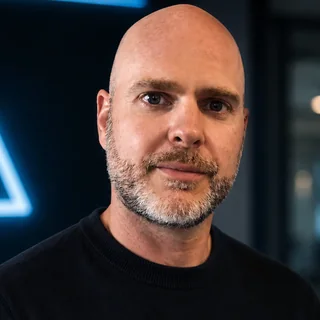
Thilo Jansen
Co-founder
A pharmacist, which is an unusual thing to find on a web tooling team and the reason every check here has to show its evidence. Defined test procedures and documented findings are the standard he brought with him.
LinkedInIf a finding is wrong
It happens — detection is heuristic in places, and a site can be correct in a way our rule did not anticipate. Every check reports the exact header, count or path it judged on, which usually makes the disagreement easy to settle. Tell us what you saw and what we said, and if the rule is wrong we will change it and note the change.
Dogfooding
This site is scored by its own rule set and publishes what it asks of others: an llms.txt, a server card, structured data, server-rendered content and a robots.txt that names agents deliberately. Run the check against webmcp-tool.com and see for yourself.